SimpleSSD is a high-fidelity SSD simulation framework designed for education and research. It builds a complete storage stack from scratch, models all detailed characteristics of SSD internal hardware and software, provides high simulation speed, and can be integrated into publicly available full-system simulators. We have verified our simulation framework with commercial SSDs, and our experiments demonstrate high accuracy of simulation results.
We build practical research platforms that connect applications, algorithms, system software, and hardware design. Our current prototypes include silicon-proven CXL controllers and fabric switches, computational storage and AI accelerators, FPGA-based memory controllers, and high-fidelity simulation frameworks. Together, they enable reproducible exploration from low-level devices to full AI and datacenter systems.
Revolutionizing Memory Capacity and Processing over Arrays

We are excited to announce the release of our latest innovation, the 4th generation high-performance accelerator and memory arrays. With this breakthrough technology, we can now support the world's largest memory capacity while enabling near-data processing capability. This development marks a significant milestone in our pursuit of more advanced and practical hardware and system research, specifically in the areas of AI and ML acceleration, cache-coherent interconnect, and memory expansion. We welcome individuals who are passionate about pioneering cutting-edge research on computer architecture and operating systems (OS) to join us on this exciting journey.
The World's First CXL-Based Disaggregated Storage-Class Memory Pool


CAMEL has developed CXL controllers and storage-class-memory-based disaggregated memory cards (DMCs) as working hardware prototypes. Our disaggregated memory-switch architecture can connect more than 500 storage-class memory modules and scale further by adding pooling switches. These platforms support hands-on research into reliable, robust, safe, and intelligent computer and memory architectures.
CAMEL's Open-Source Software
SimpleSSD [website]
Open-Source Licensed Educational SSD Simulator for High-Performance Storage and Full-System Evaluations
- DockerSSD: Containerized In-Storage Processing and Hardware Acceleration for Computational SSDs (HPCA'24)
- Amber: Enabling Precise Full-System Simulation with Detailed Modeling of All SSD Resources (MICRO'18)
- FlashShare: Punching Through Server Storage Stack from Kernel to Firmware for Ultra-Low Latency SSDs (OSDI'18)
- SimpleSSD: Modeling Solid State Drive for Holistic System Simulation (IEEE CAL)
- CEMU: Enabling Full-System Emulation of Computational Storage Beyond Hardware Limits (ASPLOS'26)
- TDMSim: Enabling High-Density and Energy-Efficient GPU DRAM Caches with 2D-Materials for Data-Intensive Applications (ISCA'26)
- N-DIPPER: A Distributed Inter-Die Peak Power Management Network for NAND Systems (HPCA'26)
- Lincoln: Real-Time 50~100B LLM Inference on Consumer Devices with LPDDR-Interfaced, Compute-Enabled Flash Memory (HPCA'25)
- SkyByte: Architecting an Efficient Memory-Semantic CXL-Based SSD with OS and Hardware Co-Design (HPCA'25)
- AnyKey: A Key-Value SSD for All Workload Types (ASPLOS'25)
- ANVIL: An In-Storage Accelerator for Name-Value Data Stores (ISCA'25)
- XHarvest: Rethinking High-Performance and Cost-Efficient SSD Architecture with CXL-Driven Harvesting (ISCA'25)
- FlexHMB: A Flexible HMB Design Toward Bufferless Mobile Flash (IEEE TCAD'25)
- SCRec: A Scalable Computational Storage System with Statistical Sharding and Tensor-Train Decomposition for Recommendation Models (IEEE TC'25)
- BeaconGNN: Large-Scale GNN Acceleration with Out-of-Order Streaming In-Storage Computing (HPCA'24)
- Midas Touch: Invalid-Data Assisted Reliability and Performance Boost for 3D High-Density Flash (HPCA'24)
- Search-in-Memory: Reliable, Versatile, and Efficient Data Matching in SSD's NAND Flash Memory Chip for Data Indexing Acceleration (IEEE TCAD'24)
- Characterizing and Optimizing LDPC Performance on 3D NAND Flash Memories (ACM TACO'24)
- HA-CSD: Host and SSD Coordinated Compression for Capacity and Performance (IPDPS'24)
- Land of Oz: Resolving Orderless Writes in Zoned Namespace SSDs (IEEE TC'24)
- BIZA: Design of Self-Governing Block-Interface ZNS AFA for Endurance and Performance (SOSP'24)
- SplitZNS: Towards an Efficient LSM-Tree on Zoned Namespace SSDs (ACM TACO'23)
- ConfZNS: A Novel Emulator for Exploring Design Space of ZNS SSDs (ISCA'23)
- OptimStore: In-Storage Optimization of Large Scale DNNs with On-Die Processing (HPCA'23)
- Decoupled SSD: Rethinking SSD Architecture through Network-Based Flash Controllers (ISCA'23)
- D-Shield: Enabling Processor-Side Encryption and Integrity Verification for Secure NVMe Drives (HPCA'23)
- Holistic and Opportunistic Scheduling of Background I/Os in Flash-Based SSDs (IEEE TC'23)
- Learning to Drive Software-Defined Solid-State Drives (MICRO'23)
- Highly VM-Scalable SSD in Cloud Storage Systems (IEEE TCAD'23)
- FSSD: FPGA-Based Emulator for SSDs (FPL'23)
- SSDe: FPGA-Based SSD Express Emulation Framework (ICCAD'23)
- Empowering Storage Systems Research with NVMeVirt: A Comprehensive NVMe Device Emulator (ACM TOS'23)
- PR-SSD: Maximizing Partial Read Potential by Exploiting Compression and Channel-Level Parallelism (IEEE TC'22)
- MQSim-E: An Enterprise SSD Simulator (IEEE CAL'22)
- Understanding and Exploiting the Full Potential of SSD Address Remapping (IEEE TCAD'22)
- ZoneLife: How to Utilize Data Lifetime Semantics to Make SSDs Smarter (IEEE TCAD'22)
- IceClave: A Trusted Execution Environment for In-Storage Computing (MICRO'21)
- GSSA: A Resource Allocation Scheme Customized for 3D NAND SSDs (HPCA'21)
- Not Your Grandpa's SSD (SIGMOD'21)
- Revamping Storage Class Memory with Hardware Automated Memory-Over-Storage Solution (ISCA'21)
- Learned Performance Model for SSD (IEEE CAL'21)
- Cosmos+ OpenSSD: Rapid Prototype for Flash Storage Systems (ACM TOS'20)
- Characterizing and Modeling Non-Volatile Memory Systems (MICRO'20)
- A Case for Hardware-Based Demand Paging (ISCA'20)
- REACT: Scalable and High-Performance Regular Expression Pattern Matching Accelerator for In-Storage Processing (IEEE TPDS'20)
- OpenExpress: Fully Hardware Automated Open Research Framework for Future Fast NVMe Devices (USENIX ATC'20)
- Check-In: In-Storage Checkpointing for Key-Value Store System Leveraging Flash-Based SSDs (ISCA'20)
- MQsim: A Framework for Enabling Realistic Studies of Modern Multi-Queue SSD Devices (FAST'18)
OpenExpress [paper] [download]
Fully Hardware Automated Open Research Framework for Future Fast NVMe Devices
NVMe is widely used by diverse types of storage and non-volatile memory subsystems as a de facto high-speed I/O interface. Industries secure their own intellectual property (IP) for high-speed NVMe controllers and explore software-stack challenges with future fast NVMe storage cards.
- DockerSSD: Containerized In-Storage Processing and Hardware Acceleration for Computational SSDs (HPCA'24)
- Hello Bytes, Bye Blocks: PCIe Storage Meets Compute Express Link for Memory Expansion (CXL-SSD) (HotStorage'22)
- OpenExpress: Fully Hardware Automated Open Research Framework for Future Fast NVMe Devices (USENIX ATC'20)
- BABOL: A Software-Defined NAND Flash Controller (MICRO'24)
- External Interfaces (Springer SLDM'24)
- FSSD: FPGA-Based Emulator for SSDs (FPL'23)
- A New NVM Device Driver for IoT Time Series Database (Micromachines'22)
- Not Your Grandpa's SSD (SIGMOD'21)
- Learned Performance Model for SSD (IEEE CAL'21)
- PIGO: A Parallel Graph Input/Output Library (IPDPSW'21)
- Behemoth: A Flash-centric Training Accelerator for Extreme-scale DNNs (FAST'21)
- Phoebe: Reuse-Aware Online Caching with Reinforcement Learning for Emerging Storage Models (arXiv'20)
GraphTensor [paper] [download]
Comprehensive GNN-Acceleration Framework for Efficient Parallel Processing of Massive Datasets
GraphTensor is a comprehensive acceleration framework for GNN computation that supports efficient parallel processing on large graphs. GraphTensor offers a set of easy-to-use GNN-specific programming interfaces, enabling its users to implement diverse GNN models. Supporting parallel embedding processing through a vector-centric approach and applying pipeline preprocessing, GraphTensor resolves the performance issues in conventional frameworks such as PyG and DGL.
- GraphTensor: Comprehensive GNN-Acceleration Framework for Efficient Parallel Processing of Massive Datasets (IPDPS'23)
- Graphite: Hardware-Aware GNN Reshaping for Acceleration with GPU Tensor Cores (IEEE TPDS'25)
- FGI: Fast GNN Inference on Multi-Core Systems (IPDPSW'25)
- The Application of GIS Technology in Accident Prevention and Management in Intelligent Traffic Management Systems (SPIE'25)
- Optimizing GNN Inference Processing on Very Long Vector Processor (LNCS'24)
OpenNVM [website] [download]
An Open-Sourced FPGA-based NVM Controller for Low Level Memory Characterization
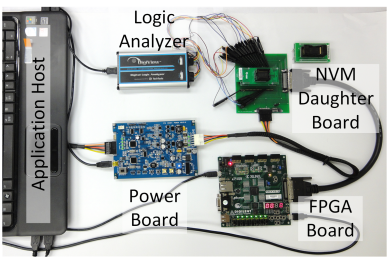
OpenNVM can cope with diversified memory transactions and cover a variety of evaluation workloads without any FPGA logic block updates. In our design, while evaluation scripts are managed by a host, all the NVM-related transactions are handled by our FPGA-based NVM controller connected to the hardware circuit board that can accommodate different types of NVM products and our custom-made power measurement board. This open scheme has been developed to generate exhaustive, empirical data of emerging non-volatile memory in a configured, programmable FPGA-based hardware prototype in order to support research on memory systems, especially non-volatile memories.
- FlashAbacus: A Self-governing Flash-based Accelerator for Low-power System (EuroSys'18)
- NearZero: An Integration of Phase Change Memory with Multi-core Coprocessor (IEEE CAL'17)
- OpenNVM: An Open-Sourced FPGA-based NVM Controller for Low Level Memory Characterization (ICCD'15)
- CDS: Coupled Data Storage to Enhance Read Performance of 3D TLC NAND Flash Memory (IEEE TC'23)
- GSSA: A Resource Allocation Scheme Customized for 3D NAND SSDs (HPCA'21)
- An FPGA-Based Hybrid Memory Emulation System (FPL'21)
- Ohm-GPU: Integrating New Optical Network and Heterogeneous Memory into GPU Multi-Processors (MICRO'21)
- REACT: Scalable and High-Performance Regular Expression Pattern Matching Accelerator for In-Storage Processing (IEEE TPDS'20)
- FastDrain: Removing Page Victimization Overheads in NVMe Storage Stack (IEEE CAL'20)
- Using Error Modes Aware LDPC to Improve Decoding Performance of 3-D TLC NAND Flash (IEEE TCAD'19)
- PEN: Design and Evaluation of Partial-Erase for 3D NAND-Based High Density SSDs (FAST'18)
- NVM-Based FPGA Block RAM with Adaptive SLC-MLC Conversion (IEEE TCAD'18)
- Invalid Data-Aware Coding to Enhance the Read Performance of High-Density Flash Memories (MICRO'18)
- Exploring Fault-Tolerant Erasure Codes for Scalable All-Flash Array Clusters (IEEE TPDS'18)
- Exploiting Data Longevity for Enhancing the Lifetime of Flash-Based Storage Class Memory (ACM POMACS'17)
NANDFlashSim [website] [download]
A cycle-accurate and hardware-validated NAND flash simulation model (open source project)
NANDFlashSim is a flash simulation model that is decoupled from specific flash firmware and supports detailed NAND flash transactions with cycle accuracy. This low-level simulation framework can enable research on the NAND flash memory system itself as well as many NAND flash-based devices such as Flash-based SSD, eMMC, CF memory card, mobile NAND flash media. We have evaluated hundreds of thousands of NANDFlashSim instances on NERSC Hopper and Carver supercomputers.
- NANDFlashSim: High-Fidelity, Micro-Architecture-Aware NAND Flash Memory Simulation (ACM Transactions on Storage (TOS))
- HIOS: A Host Interface I/O Scheduler for Solid State Disks (ISCA'14)
- Sprinkler: Maximizing Resource Utilization in Many-Chip Solid State Disks (HPCA'14)
- Triple-A: A Non-SSD Based Autonomic All-Flash Array for Scalable High Performance Computing Storage Systems (ASPLOS'14)
- Physically Addressed Queueing (PAQ): Improving Parallelism in Solid State Disks (ISCA'12)
- Understanding System Characteristics of Online Erasure Coding on Scalable, Distributed and Large-Scale SSD Array Systems (MSST'12)
- Lincoln: Real-Time 50~100B LLM Inference on Consumer Devices with LPDDR-Interfaced, Compute-Enabled Flash Memory (HPCA'25)
- ANVIL: An In-Storage Accelerator for Name-Value Data Stores (ISCA'25)
- LearnedFTL: A Learning-Based Page-Level FTL for Reducing Double Reads in Flash-Based SSDs (HPCA'24)
- SpecHD: Hyperdimensional Computing Framework for FPGA-Based Mass Spectrometry Clustering (DATE'24)
- MCMQ: Simulation Framework for Scalable Multi-Core Flash Firmware of Multi-Queue SSDs (DATE'22)
- Learned Performance Model for SSD (IEEE CAL'21)
- REACT: Scalable and High-Performance Regular Expression Pattern Matching Accelerator for In-Storage Processing (IEEE TPDS'20)
- MQsim: A Framework for Enabling Realistic Studies of Modern Multi-Queue SSD Devices (FAST'18)
- Amber: Enabling Precise Full-System Simulation with Detailed Modeling of All SSD Resources (MICRO'18)
- Exploring Parallel Data Access Methods in Emerging Non-Volatile Memory Systems (IEEE TPDS'16)
Open Storage Trace [website]
Storage traces are widely used for storage simulation and system evaluation. Since high performance SSD, flash array and NVM systems exhibit different I/O timing behaviors, the traditional traces need to be revised or collected on relatively modern systems. To address this, we are collecting different types of traces with many different combinations of devices and systems. Our trace repository distributes traces collected on Kandemir, Wilson, John and Donofrio machines under different types of parallel file systems such as Lustre and Ceph. We hope to expand the repository with additional traces that help the storage-systems and architecture communities conduct better, reproducible research.
- PEN: Design and Evaluation of Partial-Erase for 3D NAND-Based High Density SSDs (FAST'18)
- TraceTracker: Hardware/Software Co-Evaluation for Large-Scale I/O Workload Reconstruction (IISWC'17)
- Understanding System Characteristics of Online Erasure Coding on Scalable, Distributed and Large-Scale SSD Array Systems (IISWC'17)
FlashGPU [download]
FlashGPU is a MacSim-based GPU simulation model that integrates with SimpleSSD. This research framework can be basically used for exploring an emerging GPU platform that would employ flash within its discrete device. The current version of FlashGPU replaces global memory with Z-NAND that exhibits ultra-low latency. It also architects a flash core to manage request dispatches and address translations underneath L2 cache banks of GPU cores. While Z-NAND is a hundred times faster than conventional 3D-stacked flash, its latency is still longer than DRAM. We expect that diverse persistent-memory subsystems, algorithms, and controllers can be explored to address the long-latency challenges that arise when flash is placed within a large GPU-core network.
- ZnG: Architecting GPU Multi-Processors with New Flash for Scalable Data Analysis (ISCA'20)
- FlashGPU: Placing New Flash Next to GPU Cores (DAC'19)
- HBM-HBF-Centric Memory Pooling Architecture with Custom Base Die for Terabyte-Scale LLM Inference (IEEE CAL'26)
- Asynchrony and GPUs: Bridging This Dichotomy for I/O with AGIO (ASPLOS'26)
- Bancroft: Genomics Acceleration Beyond On-Device Memory (PACT'25)
- Cost-Efficient LLM Training with Lifetime-Aware Tensor Offloading via GPUDirect Storage (NeurIPS'25)
- Bandwidth-Effective DRAM Cache for GPUs with Storage-Class Memory (HPCA'24)
- BeaconGNN: Large-Scale GNN Acceleration with Out-of-Order Streaming In-Storage Computing (HPCA'24)
- GPU-Initiated On-Demand High-Throughput Storage Access in the BaM System Architecture (ASPLOS'23)
- G10: Enabling an Efficient Unified GPU Memory and Storage Architecture with Smart Tensor Migrations (MICRO'23)
- FSSD: FPGA-Based Emulator for SSDs (FPL'23)
- Revamping Storage Class Memory with Hardware Automated Memory-Over-Storage Solution (ISCA'21)
- Ohm-GPU: Integrating New Optical Network and Heterogeneous Memory into GPU Multi-Processors (MICRO'21)
- FastDrain: Removing Page Victimization Overheads in NVMe Storage Stack (IEEE CAL'20)
SystemC-based DRAMSim2 [report] [download]
SystemC interface converter (SCIC) enables DRAMSim to be integrated with comprehensive pin-level system simulation models. SCIC manages protocol differences between the DRAMSim and SystemC interfaces. SCIC also provides storage resources for modeling data movement. Additionally in this project, a pin-level protocol (Transaction Level 0) is introduced into the DRAMSim memory-system model; therefore, the memory system can be harmonized to other simulators that employ SystemC or HDL simulation.
- SCIC: A System C Interface Converter for DRAMSim (Lawrence Berkeley National Laboratory Technical Report)
CAMEL's Hardware Prototypes
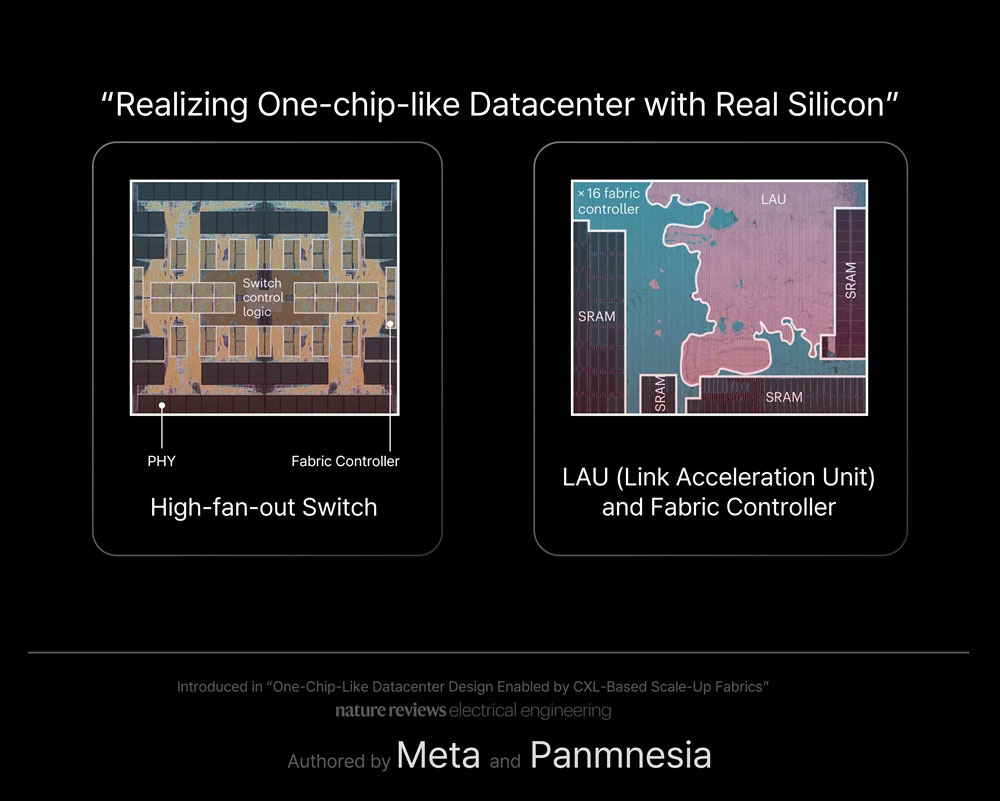
One-Chip-Like Datacenter Design Enabled by CXL-Based Scale-Up Fabrics [paper]
Nature Reviews Electrical Engineering (2026). High-fan-out switch, link acceleration unit (LAU), and fabric controller silicon supporting a proposed CXL-based scale-up architecture. Joint work by KAIST, Panmnesia and Meta.
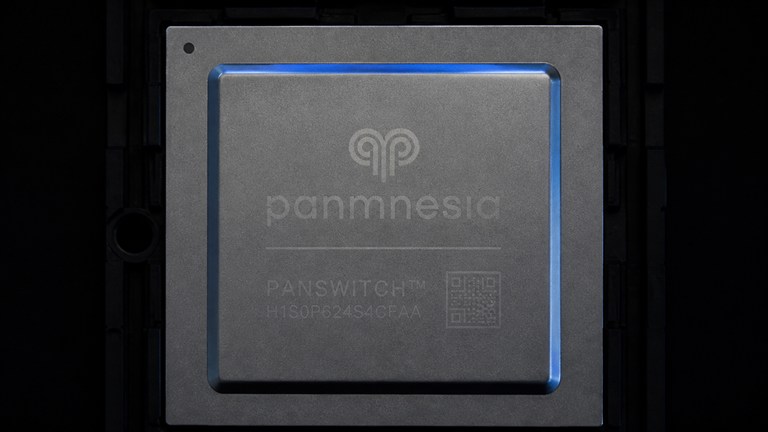
A Silicon-Proven Unified Low-Latency CXL Controller and Port-Based Routing Switch for Memory-Centric Fabrics [paper]
ISCA'26 Industry Track.
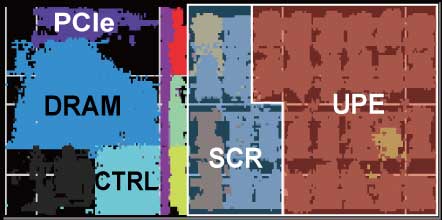
AutoGNN [paper]
Dynamically reconfigurable graph preprocessing accelerator for GNN workloads on various datasets
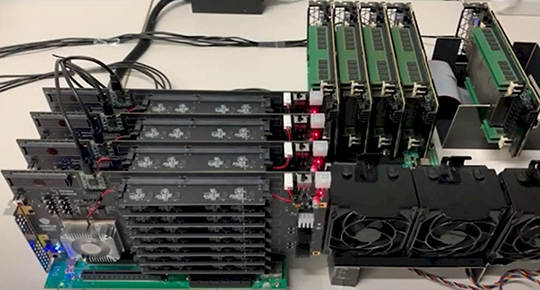
DirectCXL [paper]
World's first CXL 2.0-based full-system memory pooling framework including CXL switch, CXL CPU, and Memory expander
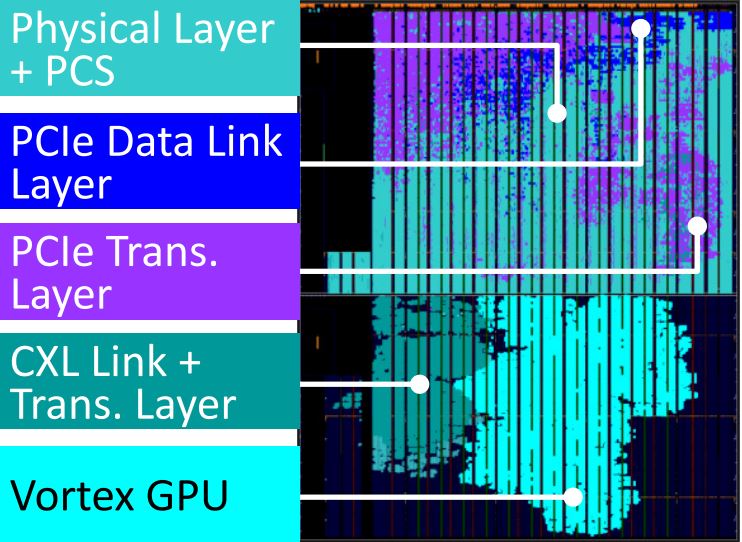
CXL-GPU [paper]
GPU storage expansion solution utilizing sub-two digit nanosecond latency CXL controller
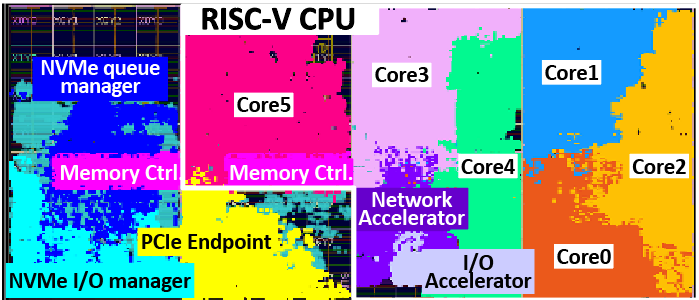
DockerSSD [paper]
Fully-flexible computational SSDs with OS-level virtualization and hardware acceleration.
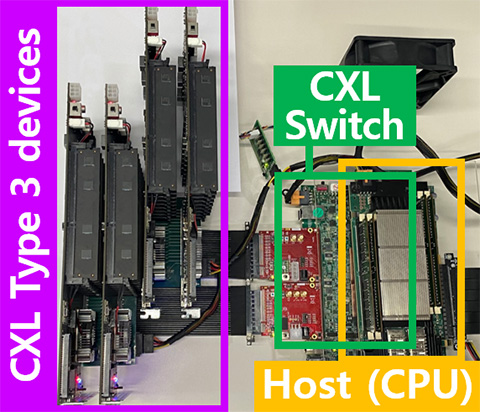
CXL-ANNS [paper]
Software-hardware collaborative memory disaggregation and computation for billion-scale approximate nearest neighbor search.
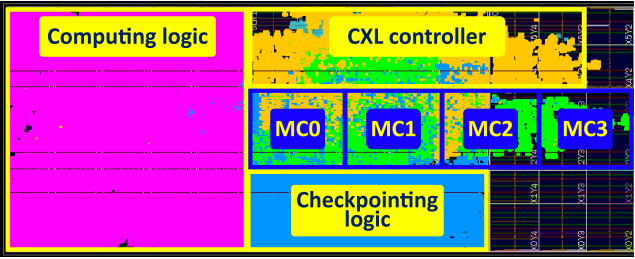
TrainingCXL [paper]
Failure tolerant recommendation system training architecture on persistent memory disaggregated over CXL.
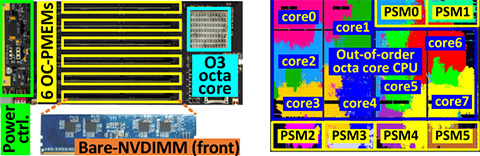
LightPC [paper]
Co-designed hardware and software for energy-efficient full system persistence.
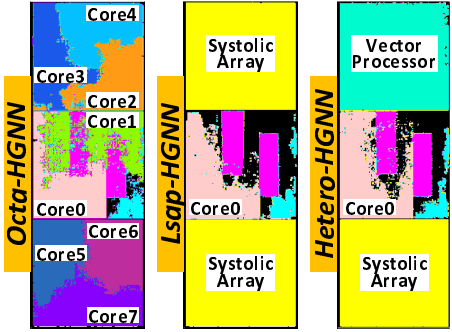
HolisticGNN [paper]
Hardware/software co-programmable framework for computational SSDs to accelerate deep learning service on large-scale graphs.
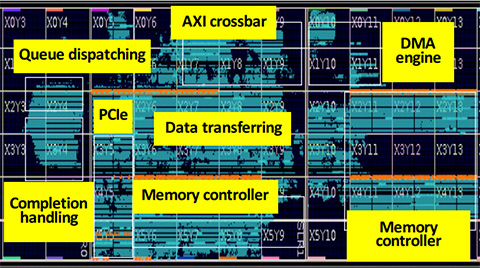
OpenExpress [paper]
Fully hardware automated open research framework for future fast NVMe devices.
Solid State Drive Simulator/Emulator
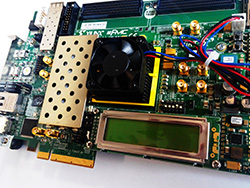
FLASHWOOD
Comprehensive Large-scale NVRAM Storage Simulation Framework
In this simulation framework, NVRAM software stack on multi-channel architecture are fully implemented, and diverse parameters/algorithms are reconfigurable (e.g., buffer cache, NVMHCIs, flash drivers, flash translation layers, physical layouts). Hardware components are emulated in a cycle-level by multiple NANDFlashSim instances, DRAM simulation instances, and virtual channel and controller modules. Flashwood can also evaluate dynamic energy and power consumption by catching all the different components' activities. The code for the flash software in the framework and device simulation code are around two hundreds thousand of lines and ten thousand of lines, respectively.
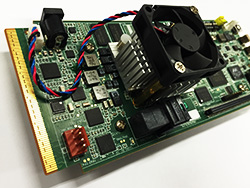
CoDEN
A Hardware/Software CoDesign Emulation Platform for SSD-Accelerated Near Data Processing
CoDEN is a novel hardware/software co-design emulation platform, which not only offers flexible/scalable design space that can employ a broad range of SSD controller and firmware policies, but also capture the details of entire software/hardware stacks for SSD-accelerated near data processing. Our CoDEN can be connected to a host through PCI Express (PCIe) interface, a high performance memory bus, and recognized by the host as a real SSD storage device.
ASURA
SSD emulation kernel driver
The SSD emulation kernel driver provides a logical volume to native file systems (e.g., Windows NTFS, EXT4) as a pseudo SSD device. Virtual channels and cycle-level NAND flash simulation instances of Asura model the actual runtime in cycle accurate by hooking kernel I/O dispatch routines. To enable large-scale SSD emulation, the driver only stores metadata of kernel modules, data of flash firmware and device simulation models -- omits actual data contents. In addition, Asura can be initiated as multiple driver instances in order to emulate an SSD RAID system. Asura has been implemented by a filter driver (WDM) for Windows (NTFS) and loadable kernel module for Linux (EXT4).
